
Scaling Laws: The Equation That Predicted the Future of AI
A 2020 OpenAI paper proved that AI capability scales predictably with compute, and that most teams were training their models wrong.
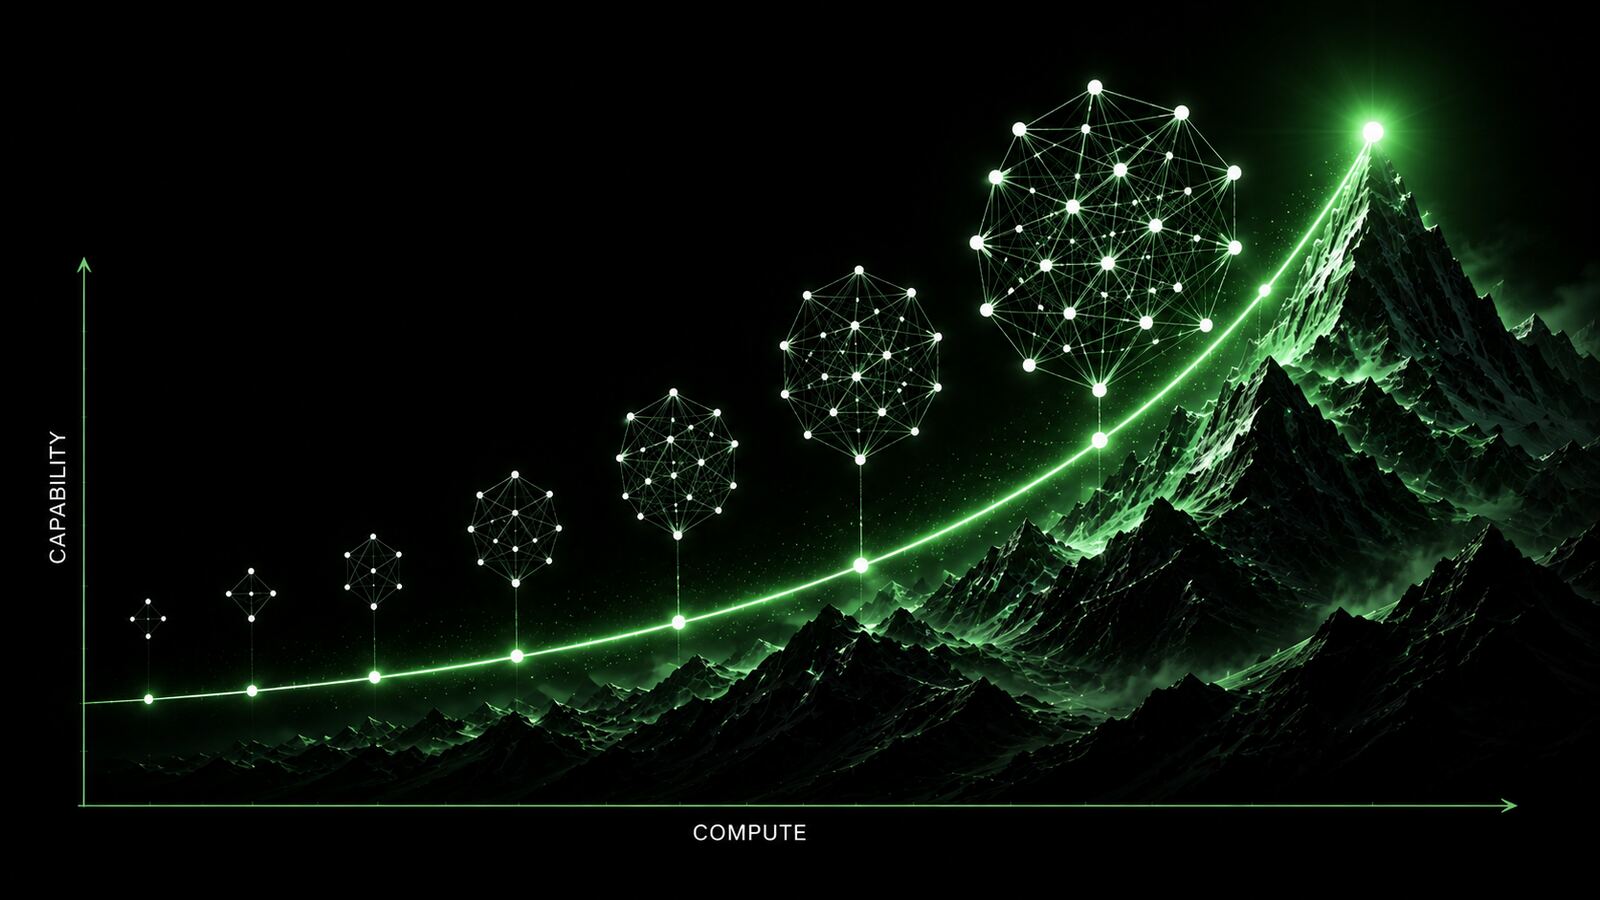
In January 2020, Jared Kaplan, Sam McCandlish, and colleagues at OpenAI published "Scaling Laws for Neural Language Models." The paper demonstrated something researchers had suspected but not rigorously established: the performance of language models follows power laws with the scale of compute, model size, and dataset size. Double the compute, and performance improves by a predictable amount. The relationship held over many orders of magnitude. The laws were empirical, derived from measurements, not first principles, but they were remarkably consistent.
The practical implication was startling. If you knew the scaling laws, you could predict how a model would perform before training it. You could decide in advance whether a given training run was worth the compute budget. You could extrapolate from small experiments to large models. For the first time, AI capability was something you could forecast rather than merely discover. The scaling hypothesis, that more compute and data would reliably produce more capable models, shifted from intuition to quantified empirical law.
In March 2022, Hoffmann and colleagues at DeepMind published the paper that became known as Chinchilla. They showed that the Kaplan scaling laws had systematically underweighted the importance of training data relative to model size. GPT-3, with 175 billion parameters, had been trained on far less data than was optimal for its compute budget. A 70-billion-parameter model trained on twice as much data would outperform it. Chinchilla itself, 70B parameters trained on 1.4 trillion tokens, exceeded GPT-3's performance while being smaller and cheaper to run.
The Chinchilla correction reshuffled the field. Llama, Meta's open-source model family released in 2023, used Chinchilla-optimal training (smaller models trained on more data) and produced models competitive with GPT-3 at a fraction of the compute cost. The focus of scaling research shifted from "make the model bigger" to "find the optimal model-to-data ratio for a given compute budget." Scaling laws became the foundation of a rigorous engineering discipline for AI development.
Scaling laws are now a standard tool at AI labs. They inform decisions about training run size, data collection strategy, and model architecture before a single GPU is spun up. They also raised an uncomfortable question: if capability scales reliably with compute, then the labs with the most compute will reliably build the most capable systems. Scaling laws did not just predict the future of AI: they described the mechanism by which the field's power would concentrate. That implication is still being processed.
What it actually meant
Scaling laws are empirical, not derived from first principles, but they held over many orders of magnitude. They shifted AI capability from something you discover to something you forecast. The Chinchilla correction showed that the dominant intuition, larger model equals better model, was wrong: the optimal model-to-data ratio matters as much as absolute size. Most frontier models before 2022 were undertrained relative to their compute budget.
What enterprises get wrong today
Enterprises take scaling laws as justification for always using the largest available model. This misreads the result. Scaling laws describe optimal training, not optimal deployment. For most enterprise inference tasks, a smaller well-trained model beats a larger poorly-matched one. The cost-quality frontier is not a single point: it is a curve, and the optimal point depends on your latency and cost requirements.
Related capabilities
More from Mathematics
Ask about this story
Scaling laws turned AI capability from something you discover into something you forecast. And Chinchilla proved that GPT-3, one of the most expensive training runs in history, was using its compute inefficiently. What would you like to explore?